Models that learn what each user does and suggest the next offer, product or activity.
It covers recommendation models, personalised offers, location and interest matching and measured results.
What you can do
Recommendation models
Suggestions from preferences and behaviour.
Personalised offers
Offers built from usage patterns.
Location and interest matching
People matched to what is near and relevant.
Measured results
Engagement tracked against a baseline.
The flow, end to end
- Collect signals with consent
- Build user profiles
- Train the model
- Serve the suggestion
- Compare with a control group
- Retrain on new data
What you receive
Named outputs. Each one is yours to keep.
What you decide, and what we need
You decide
- Which signals are allowed
- Where suggestions appear
- What success means
- What is never used
We need from you
- Usage and transaction history
- A place in the product to show it
- A measure of success
How we measure it
Agreed before the build. Reported after every change.
What buyers ask us
Banks, operators and public bodies ask the same six questions.
"Can we test your AI with our own data?"
Yes. Every system ships with a test set built from your cases, and the report is yours.
"Where does our data go?"
Nowhere. Models run on your servers, a private cloud or a national cloud that you choose.
"Who is accountable for a decision?"
A person on your side. The system prepares the work. People approve what affects rights or money.
"Will we see when the model changes?"
Yes. Updates are tested on your cases first, and recorded.
"What if it fails?"
A fallback procedure is agreed before launch, and rehearsed.
"Are you certified?"
Our delivery is certified to ISO/IEC 27001 and ISO 9001:2015. We do not hold ISO/IEC 42001.
What we will not promise
A vendor who promises these has not run a model in production.
- An AI system that never makes a mistake
- A system nobody can attack
- Delivery in a fixed number of weeks before we have seen your data
- A saving we have not measured
- Bangla results equal to English without testing them
- AI that needs no human oversight
How it works
- Collect signalsUsage, purchases and location, with consent.
- Build the modelIt learns what similar users did next.
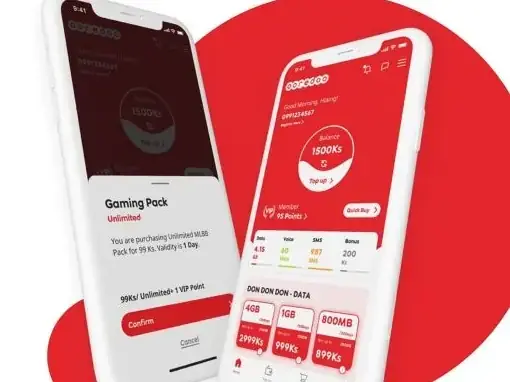
- Serve the offerSuggestions appear in the app, in real time.
- MeasureResults are compared with a control group.
What can go wrong, and what we do about it
Too little data
We start with simple rules and move to models when the data supports it.
Offers feel intrusive
Sensitive signals are excluded by design.
No proof it works
Every change is tested against a baseline.
How we run the project
Where it fits
We tell you before the project starts, not after.
Where it works well
Consumer apps, telecom self-care, loyalty programmes and retail.
Where it works badly
Products with too few users to learn from.
What you'll get
- A working system on your own data
- An accuracy report on your own cases
- Access rules and a full audit log
- Training for the people who will use it
- Documents your auditors can read
How it starts
Find out if it is worth building
A short, fixed-scope review of your data, systems and rules.
- Interviews with the people who do the work
- Review of data and systems
- A ranked list of use cases with effort and cost
- A written recommendation
See it working on your own data
A working system for one use case, built on your real data.
- One agreed use case
- A working system, not slides
- An accuracy or performance report
- A costed plan for production
Go live in your environment
The full build: integration, security testing, training and go-live.
- Integration with your systems
- Security testing before launch
- Training and handover documents
- Go-live support
Keep it running and keep it safe
Monitoring, patches, model updates and reports for as long as the system runs.
- Monitoring and alerting
- Patches and updates
- Model and data updates
- Regular reports for audit
Where we have done it
What you should know
Does our data leave our network?
No. The model runs on your servers, a private cloud or a national cloud. We agree the location in writing before work starts.
Which models do you use?
Open models and commercial ones. We pick per workload and explain the choice, the hardware and the running cost in writing.
How do you know the answers are right?
We test the system on your own cases before launch. You get the accuracy report. Unclear cases go to a person.
Who makes the final decision?
A person. The system prepares the work and shows its source. People approve anything that affects rights or money.